Tag: watermarking

7 jots

Subscribe to this tag
RSS 2.0 https://jottings.vishalvshekkar.com/tags/watermarking/feed.xml
Atom 1.0 https://jottings.vishalvshekkar.com/tags/watermarking/atom.xml
JSON Feed https://jottings.vishalvshekkar.com/tags/watermarking/feed.json
Vishal V. Shekkar
Vishal V. Shekkar I declare verified!
@vishalvshekkar
Sun, 16 Aug 2026 05:03:32 GMT

All that being said, the math behind watermarking is quite remarkable.

Using the entropy in human language to encode some "unseen" information to communicate something is quite novel.

The artifact linked below is by Thariq from the Claude team. It illustrates how watermarking works and how reliable it is for each type of generative model use case.

https://claude.ai/code/artifact/803916fd-3bc1-465f-8738-d...

Vishal V. Shekkar
Vishal V. Shekkar I declare verified!
@vishalvshekkar
Sun, 16 Aug 2026 04:07:37 GMT

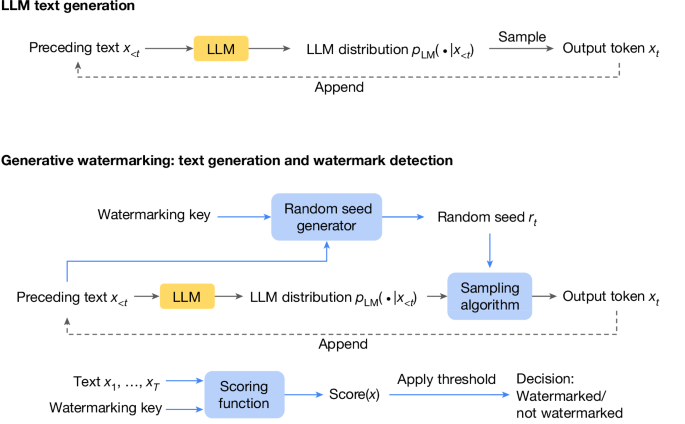
Anthropic uses SythID-Text approach for watermarking popularized by Google Deepmind, and tested within Gemini. This method uses tournament sampling to pick the next token from a possible set of tokens (size dependent on available entropy for that next token.)

SynthID like many other watermarking technique uses a pseudorandom key to run the tournament knockout on the highly-likely candidates for the next token.

In principle, generative text watermarking can be extended from just provenance detection ('this came from model E') to cryptographic fingerprinting ('this came from account AGHRS125') or even multi-bit attribution ('this encodes identifier Y').

Model providers may use different keys per account instead of one key across all generations. Possibly using a pseudo-random function that mixes the master key with a user identifier so they may generate it deterministically during detection/attribution.

Another, more novel way is to encode some identifying information as binary payload into the watermark itself. watermark payload = providerID | modelID | accountID | requestID

Just the way the plain watermark is encoded in the statistical manner determined by SynthID in the next-token available entropy space, that watermark itself could carry accountID and a lot more info. This way, any meaningful length of text generated by a model could have the signature of who prompted its generation.

This is an extremely powerful tool, which I'm sure, would be exploited to its depths in the near future.

Note: The SynthID paper itself doesn't get into personal attribution. But, there are other mechanisms built specifically with the objective of identification.

Vishal V. Shekkar
Vishal V. Shekkar I declare verified!
@vishalvshekkar
Sun, 16 Aug 2026 03:49:04 GMT

While I understand why watermarking is important to identify content originating from a generative model and establish provenance, it is yet another tool in that may be deployed in mass surveillance with ability to tie generated content to specific account/groups/geography.

As much as I hate AI slop, and the deeply disturbing side of generative AI like deepfakes and mass propaganda it can enable, a tool to fight that can also be used as a tool for also targeting individuals.

Vishal V. Shekkar
Vishal V. Shekkar I declare verified!
@vishalvshekkar
Thu, 13 Aug 2026 07:48:16 GMT

LLM watermarking turns the model’s linguistic entropy into bandwidth. Wherever the model has multiple plausible ways to say the same thing, those degrees of freedom become a channel through which a hidden (watermarking) signal can be transmitted.

Vishal V. Shekkar
Vishal V. Shekkar I declare verified!
@vishalvshekkar
Thu, 13 Aug 2026 07:46:37 GMT

Advanced LLM watermarking is closer to spread-spectrum radio than to stamping text with a signature. The language itself is the carrier; a weak cryptographic signal is spread across thousands of otherwise natural token choices. To everyone listening normally, it’s just language. With the right key, you can correlate against the hidden signal and pull it out of the noise.

The text is not where the watermark sits, it is the carrier wave. The watermark lives in tiny coordinated deviations in how that carrier is generated. Without the key they look like ordinary sampling noise. With the key, they line up coherently into a signal.

Vishal V. Shekkar
Vishal V. Shekkar I declare verified!
@vishalvshekkar
Thu, 13 Aug 2026 07:13:27 GMT

Watermarking an LLM's output, in Kirchenbauer et al., is basically turning token generation into a dynamic casino where the house secretly nudges the model toward green tokens. A z-test detector regenerates those context-dependent green sets and asks whether the generated text landed on them far more often than chance would plausibly explain. It isn't detecting “AI style”; it's detecting an intentionally planted statistical bias.